Infinite Slop: Inside the Real-Time AI Livestream
Last updated Sep 3, 2026
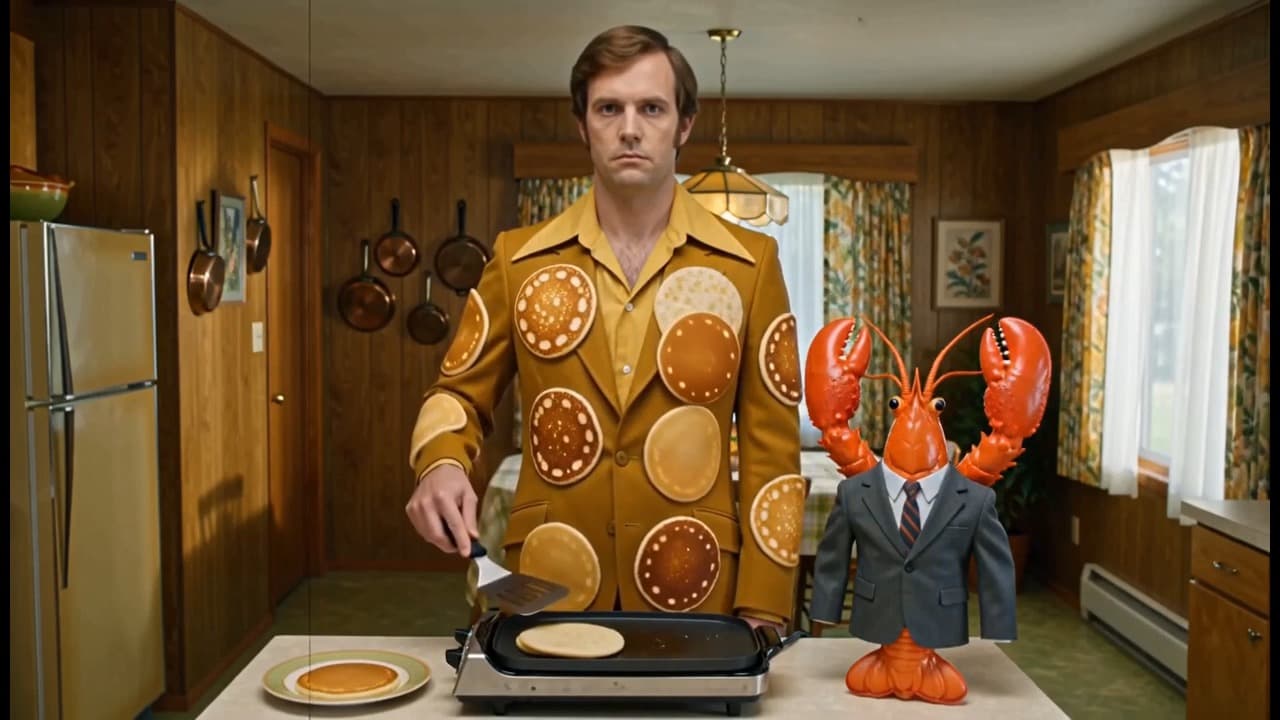
Infinite Slop is a livestream that never stops generating. An AI model produces new video before the previous clip finishes playing, and viewers steer what happens next by typing prompts into the chat. Built by indie developer Pieter Levels on fal.ai's H3 Max Live model, it drew roughly 37,000 viewers on its first day at the end of August 2026 and reached tech press within a week, because generation finally outran playback.
What changed: generation got faster than watching
For most of 2026, AI video tools produced short clips faster than a human could shoot and edit the same footage by hand, but still slower than the clip itself ran. A 5-second video might take two to five minutes to render. That gap is why AI video stayed a batch process: you asked for a clip, you waited, you got a file back.
fal.ai's H3 Max Live changes the math. Built on a fine-tuned version of Minimax's H3 model and optimized on fal's own inference stack, it generates 15 seconds of usable video in under 10 seconds, according to coverage from Latent Space's AINews newsletter, which called the model roughly 35 times faster than the original release. A separate writeup from Steal What Works put the improvement at closer to 50x on shorter clips, generating 5 seconds of 768p video in under 3 seconds. Either figure crosses the same line: the model can produce the next segment before the current one ends, which is the one condition a livestream actually needs.
This is a narrower claim than it sounds. The original Minimax H3 release, before fal's optimization pass, took two to five minutes to render 15 seconds of footage, which is standard for the current generation of video diffusion models. fal did not train a faster model from scratch. It took an existing one and rebuilt the inference path around it, trading some quality and consistency for latency. The tradeoff shows on screen: characters shift proportions between cuts, backgrounds warp when the camera implies motion it cannot fully render, and continuity between one generated segment and the next is loose at best. None of the coverage treats that as a surprise. The point being made across every outlet is that the speed threshold, not the image quality, is what makes a livestream possible at all.
How chat-directed video actually works
Infinite Slop's mechanic is simple to describe and unusual to watch. A clip plays. Viewers in the chat type a prompt, prefixed with an instruction like the model expects, describing what should happen next: change the location, swap the season, turn the scene into a different genre entirely. The system takes the strongest or most recent prompt, generates a new segment that tries to continue visually from the last frame, and plays it the moment it is ready. There is no script and no fixed runtime. The show is whatever the crowd asked for five seconds ago.
Levels was not the first to try this. Latent Space's coverage credits an earlier H3 Max livestream by Marc Antoine and Rehan Sheikh with proving the format could hold together technically before Levels built his own version on top of it. Levels's contribution, and the reason his version spread, was making the loop participatory: instead of passively watching a generated stream, viewers could argue with each other in chat over what happened next, and the model would follow whichever prompt won out.
The practical effect is closer to a group storytelling session than a produced show. One prompt asks for the scene to become a 1980s comedy sketch. The next asks for a live streamer walking around San Francisco pointing out landmarks. A third rewrites the whole thing into an anime sword fight. Nothing forces continuity between requests beyond the model's own attempt to carry the last frame forward, so the feed reads less like a story and more like a crowd fighting over the remote in real time, except the remote rewrites the show itself rather than switching channels.
The numbers behind the launch
Levels reported roughly 37,000 people watched on the first day, with concurrent viewership peaking around 400 at a time and the launch writeup drawing more than 120,000 page views, according to Steal What Works' reporting. There is no confirmed monetization: the stream currently runs free with fal covering the inference cost. Steal What Works estimates the compute bill at around $207,000 a month if the stream ran nonstop at standard 768p rates, a number nobody involved has confirmed or denied publicly. fal is a company Levels has invested in and already relies on for his other AI products, which the outlet flagged as a real but undisclosed commercial alignment rather than a straightforward sponsorship.
Put next to a normal product launch, those numbers are small. 37,000 first-day viewers and 400 concurrent is a modest Twitch stream by any standard measure, nowhere near what a major platform launch pulls. What made it news was not the audience size, it was that the audience was watching something no human had produced ahead of time, generated live, responding to their own typed instructions within seconds. The gap between "small stream" and "real-time generative broadcast that nobody scripted" is where the coverage actually sits.
What the press and AI community are saying
Coverage split fast between the technical milestone and the actual content on screen. Latent Space's AINews called the footage itself "pure slop," writing that the achievement is the technological floor for real-time generative video, not its ceiling, meaning the interesting use cases have not been built yet. AI Valley framed it as a shift in what media even is, quoting the idea that "instead of making a finished piece of media and then distributing it, the media itself can keep changing based on what the audience does," and describing the result as media that behaves "less like a file and more like a living thing."
The format reached general tech audiences fast. TWiT's Intelligent Machines podcast covered it on episode 886, aired September 3, alongside that week's other AI stories, with hosts Leo Laporte, Jeff Jarvis, and Paris Martineau discussing it as one entry in a broader run of consumer AI products shipping faster than anyone can evaluate them. That a niche livestream experiment reached a mainstream tech podcast within a week of launch is itself a data point on how quickly real-time generative video moved from research demo to something people can watch tonight.
Why the feed disappears the moment you look away
The one property every write-up mentions and nobody solves is that Infinite Slop, like the format it launched, does not keep a record. Once a clip plays, it is gone. There is no archive of what the crowd asked for, what prompt produced what scene, or which viewer's idea shaped the story. For a format built entirely on audience participation, that means the most interesting artifact, the actual prompt history, disappears by design.
One project addressing that gap directly is a mirror running at theinfiniteslop.com, which restreams the same kind of chat-directed AI feed but keeps every clip and the prompt that generated it, archived and searchable rather than thrown away once it airs. It is a small, practical answer to the one complaint that shows up in nearly every piece of coverage: that a format built on what the audience wanted has no record of what the audience actually asked for.
What this means if you are building with AI video
The practical takeaway for anyone evaluating AI video tools right now is narrower than the headlines suggest. A 35x to 50x speed jump on one model, on one company's inference stack, does not mean every video model is suddenly real-time. It means the ceiling on what real-time generative video can do just moved, and the gap between "fast enough to livestream" and "fast enough to be useful for real work" is closing faster than most teams have planned for. If your own AI video workflow is still built around waiting for a render queue, this is the moment to check whether the model you are using has closed that gap yet, because at least one has.
FAQ
What is Infinite Slop?
Infinite Slop is a livestream created by indie developer Pieter Levels that runs on fal.ai's H3 Max Live model, which generates new video faster than the previous clip finishes playing. Viewers type prompts into the chat to steer what happens next, so the show has no script and no fixed runtime.
How does Infinite Slop generate video in real time?
It runs on fal.ai's H3 Max Live model, a fine-tuned version of Minimax's H3 optimized on fal's own inference stack. Coverage from Latent Space's AINews puts the speed improvement at roughly 35 times faster than the original model, generating 15 seconds of video in under 10 seconds, fast enough that a new segment is ready before the current one finishes playing.
Who built Infinite Slop?
Indie developer Pieter Levels built Infinite Slop on fal.ai's H3 Max Live model. Levels credits an earlier H3 Max livestream by Marc Antoine and Rehan Sheikh with proving the underlying format could work technically, before he built his own participatory version on top of it.
How many people watched Infinite Slop?
Levels reported roughly 37,000 viewers on the stream's first day, with concurrent viewership peaking around 400 at a time, according to reporting from Steal What Works. The launch writeup itself drew more than 120,000 page views.
Can I watch Infinite Slop replays or past clips?
The original Infinite Slop stream keeps no archive. Once a clip plays, it is gone, with no record of the prompt that produced it. A separate project, theinfiniteslop.com, restreams the same kind of chat-directed AI feed and keeps every clip along with the prompt that generated it, archived and searchable.